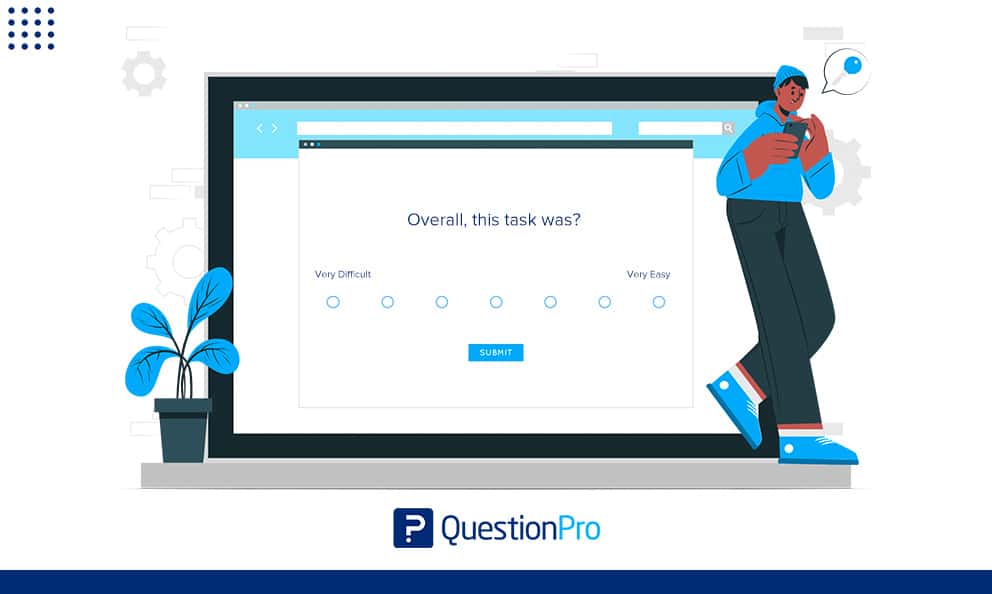
The Single Ease Question, or SEQ, is a one-item, 7-point rating scale asked right after a user attempts a task, measuring how difficult or easy that task felt. Researcher Jeff Sauro popularized it after years of testing it against longer post-task questionnaires.
Most usability metrics tell you whether a task was completed. The SEQ tells you how it felt to complete it, which is a different and often more revealing signal.
Because it is a single question, it takes participants only seconds to answer, and it can be dropped into almost any usability test, website flow, or QuestionPro survey without adding friction.
In this guide, we’ll explain what the SEQ measures, how to word it correctly, and where it fits alongside other usability metrics.
What is the Single Ease Question?
The Single Ease Question is a standardized usability metric that asks a user to rate how hard or easy a specific task was, immediately after they attempt it. It captures a subjective, in-the-moment reaction rather than an overall impression of a product.
The standard wording is:
Overall, how difficult or easy was [the task] to complete?
Respondents answer on a 7-point scale, where 1 means very difficult and 7 means very easy. Only the two endpoints are labeled, since MeasuringU’s research found that labeling every point reduces the scale’s sensitivity.
The SEQ is asked after each task in a usability session, not once at the end. This keeps the feedback specific to that task and fresh in the participant’s memory, rather than blended with impressions of everything else they just did.
Also check: The differences between a 5-point vs. 7-point Likert scale.
How does the SEQ differ from the System Usability Scale?
The SEQ measures one task. The System Usability Scale (SUS) measures a whole product or session using ten questions asked at the end.
Both use a Likert-style rating format, which is a survey scale that asks respondents to rate agreement or ease on a numbered range. Beyond that similarity, they serve different purposes.
- The SEQ is given after every task, so you can compare which specific steps caused the most friction.
- The SUS is given once, so it reflects an overall impression rather than any single interaction.
- The SEQ takes seconds to answer, while the SUS takes a few minutes.
- The SEQ is more useful for pinpointing where in a flow people struggle. The SUS is more useful for benchmarking a product’s overall usability against past versions or competitors.
Research summarized by the Nielsen Norman Group has found that single-item post-task ratings like the SEQ correlate about as well with task success and completion time as longer, multi-item questionnaires, while asking far less of the participant.
Discover more: System Usability Scale survey template.
When should you use a Single Ease Question?
Use the SEQ any time you need a fast, low-friction read on how one specific task felt, rather than an assessment of an entire product or relationship. Six situations come up most often.
- Usability testing.
Measure how hard each step in a checkout, sign-up, or onboarding flow feels to real users. - Customer experience research.
Gauge how easy a specific interaction, like requesting a quote or filing a claim, felt for the customer. - Product and app testing.
Compare task difficulty across app versions or prototype iterations. - Healthcare communication.
Check how easily patients understood a set of instructions or completed an intake form. - Market research.
Assess how easy it was to compare or choose between products during a shopping simulation. - Education.
Gauge how difficult students found a specific assignment, tool, or learning module.
How do you write a good Single Ease Question?
A good SEQ keeps the standard wording intact and only swaps in the specific task name. Changing the scale or the phrasing breaks comparability with published usability benchmarks.
Use this template:
Overall, how difficult or easy was it to [specific task, for example ‘request a quote’] to complete?
Two additions make the question more useful. First, ask “why” as an open-ended follow-up whenever someone rates a task 4 or below, since that comment usually points straight to the friction point. Second, keep the task description specific. A vague task label like “using the site” produces a vague, less actionable score.
How do you analyze and report SEQ results?
An SEQ score is only useful in context. A single average tells you little on its own, so compare it against a benchmark or against other tasks in the same study.
MeasuringU’s published benchmarks put the typical SEQ average around 5.5 on the 7-point scale, so scores clearly below that flag a task worth investigating. Beyond the average, look at three things: the spread of scores across participants, the open-ended “why” comments tied to low scores, and how the score for one task compares to others in the same flow.
This is where the SEQ earns its place as a diagnostic tool rather than just a satisfaction score. It tells a team exactly which task to fix next, not just whether users were happy overall.
Where is the SEQ used outside of software usability testing?
The SEQ started in software usability testing, but its simplicity has carried it into other fields that need a fast read on perceived difficulty.
- Customer experience teams use it after specific interactions, like resolving a support ticket, to see how effortless the process felt.
- Healthcare researchers use it to check how easily patients understood medical instructions or completed a procedure.
- Market researchers use it to evaluate how easy a product or service was to use, which often connects to purchase intent.
- Educators use it to see how difficult students found a specific lesson, tool, or assignment.
In each case, the core value stays the same: one clear question, asked at the right moment, tied to one specific task.
Common mistakes to avoid when using the SEQ
A few missteps quietly weaken SEQ data. Watch for these:
- Asking the SEQ once at the end of a long session instead of after each task, which blurs which step actually caused the friction.
- Rewording the scale or reversing the polarity, which breaks comparability with published benchmarks.
- Skipping the “why” follow-up on low scores, which leaves teams with a number but no explanation.
- Using a vague task description, which produces a score no one can act on.
Survey tools that support post-task triggers and open-ended follow-up logic, such as QuestionPro’s survey software, make it straightforward to fire an SEQ after a specific action and branch into a “why” question automatically when the score is low.
The SEQ works best as one part of a bigger picture
A single ease question will not tell you everything about how usable a product is, and it was never meant to. What it does well is point directly at the moments inside a task where people struggle, in a way that takes almost no effort for the person answering it.
Pairing SEQ data with completion rates, time on task, and a periodic SUS score gives a fuller, more actionable view of usability over time.
Frequently Asked Questions (FAQs)
Published MeasuringU benchmarks put the average SEQ score around 5.5 out of 7. Scores consistently below that for a specific task suggest real friction worth investigating with a follow-up “why” question.
Not entirely. The SEQ works best for diagnosing individual tasks, while the SUS gives a broader, session-level usability benchmark. Many research teams use both together for a complete picture.
Usability research commonly uses five to eight participants per round for qualitative insight, though larger benchmarking studies use dozens of respondents for statistically stable averages. The right number depends on how confident you need the score to be.
Yes. Healthcare, customer experience, market research, and education teams all use the SEQ to measure how easy a specific task or interaction felt, not just software flows.
Anonymity is not required, but it often increases honesty, especially in employee-facing or internal tool testing where participants may hesitate to criticize a colleague’s design work.